
技术 SEO 与抓取索引
共 141 篇文章 · 第 4 / 15 页
-
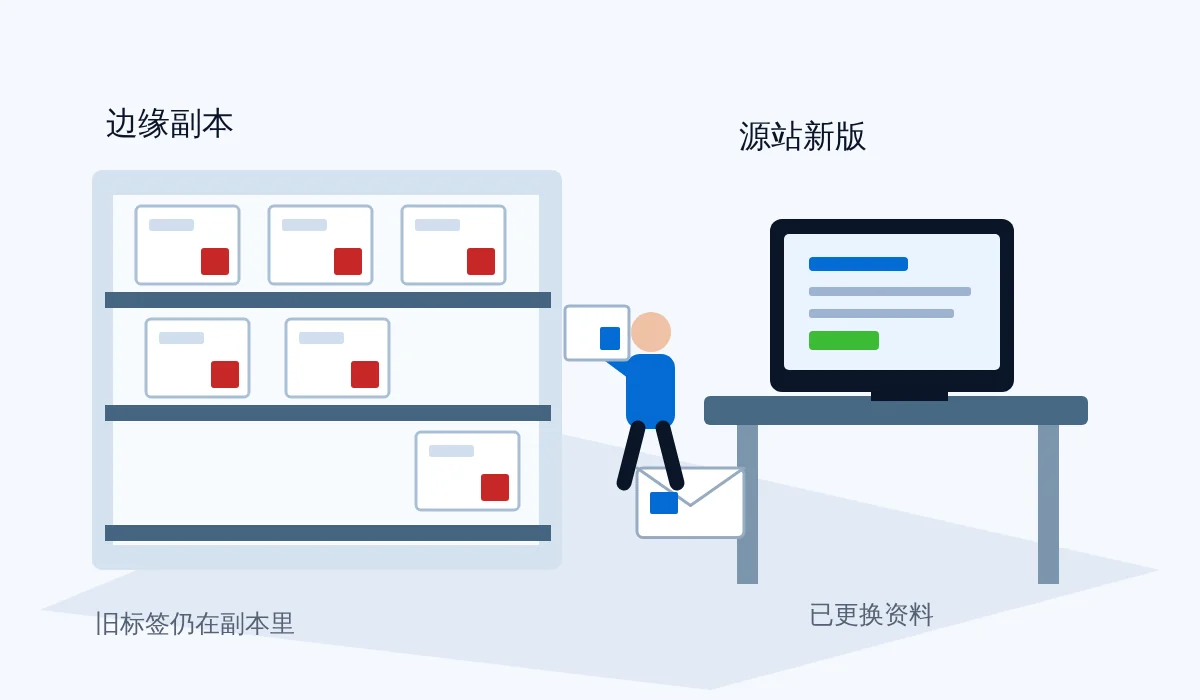
后台已取消noindex,公网还在禁止收录:CDN旧缓存怎样查
取消noindex后公网仍受限,先保存同URL的HTTP头与HTML。用正文版本、缓存迹象和源站对照,区分旧副本与边缘追加规则,说明缓存失效范围及恢复索引前的检查边界。
-
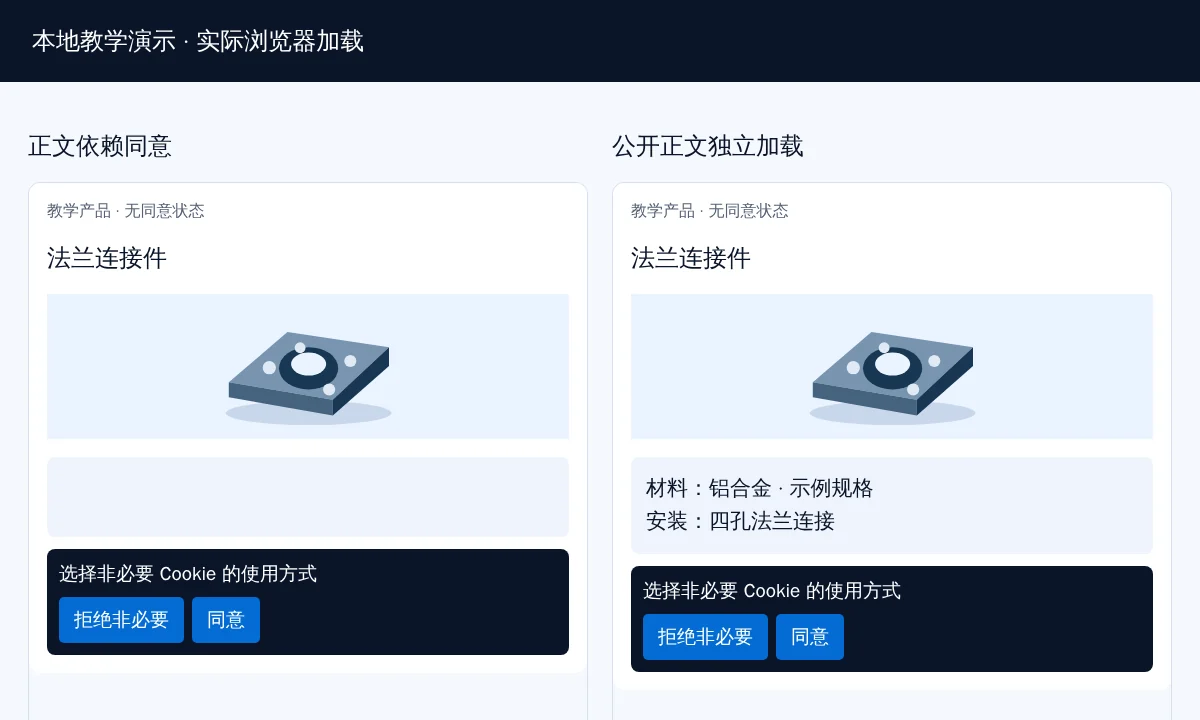
必须同意Cookie才能看正文?先把公开内容与追踪脚本拆开
未选择或拒绝营销Cookie后,产品说明也该能正常读取。本文区分遮罩与正文未加载,说明Google跨页状态限制,并给出内容脚本拆分、深链及三种同意状态的检查方法。
-
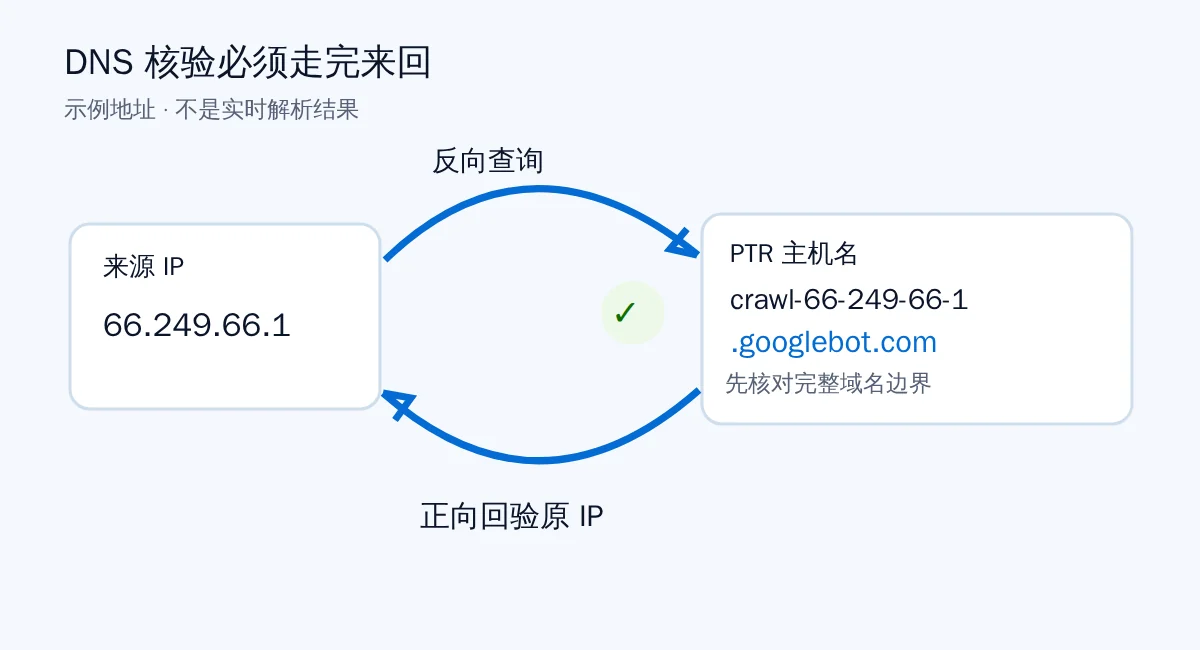
日志写着Googlebot就能放行?把反向DNS和正向验证做完整
别凭User-Agent放行Googlebot。本文从代理后的可信来源IP、PTR域名边界和正向回验讲起,说明官方IP范围的使用、超时处理及有限放行检查,不把身份验证当作收录保证。
-
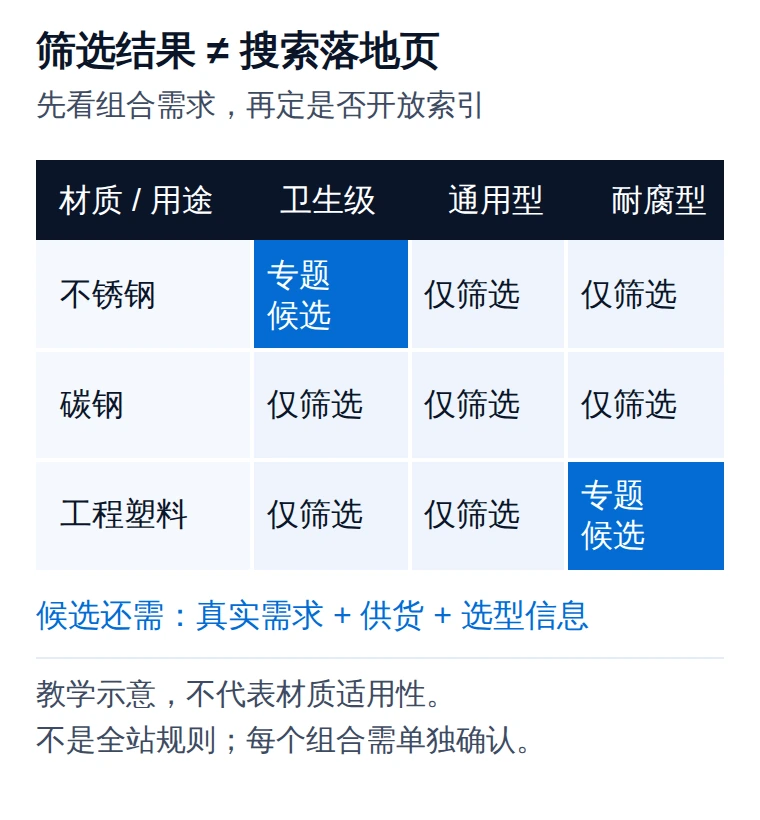
筛选页越多越好吗?材质、尺寸与用途组合怎样做SEO
材质、尺寸与用途筛选不必全部收录。按采购需求、产品集合和维护能力确定索引准入,分清canonical、robots.txt与noindex,并检查空结果页和参数抓取。
-
After submitting the sitemap | Why does Google only index some pages?
Investigate gaps between sitemap submissions and indexed pages through file structure, internal links, content quality, server access and blocking rules.
-
Will Google bots place orders on independent websites? | The truth about debunking fake orders
Distinguish Googlebot crawling from shopping activity, investigate suspicious cart events and review bot identification and protective measures.
-
Google Indexing Strategy: Diagnose Discovery, Crawling and Quality
Audit indexing by page type and stage: discovery, crawling, canonical choice and search visibility. Use sitemaps and URL Inspection without fixed indexing promises.
-
JavaScript SEO for Vue and React: Diagnose Rendering and Indexing Problems
Diagnose JavaScript SEO issues on Vue and React sites, compare crawled and rendered content and review implementation choices for accessible pages.
-
Do .shop, .store, .app, .ai and .biz domains rank differently from .com?
Since ICANN opened new generic top-level domains (New gTLDs) in 2012, more than 1,500 new suffixes have flooded the market, from .shop and .ai to .
-
Google does not index infinite scroll pages. | Must we revert to pagination?
In the past three years, over 58% of websites worldwide have adopted infinite scroll design (Data source: PageTraffic 2023)